My blog, savalione.com, is geographically distributed via Geo-DNS. Multiple nodes in different regions host the blog, and some of them host additional open-source, free-of-charge services.
One of the services I host is a Zig community mirror.
I've been hosting this mirror for the past year on the ru-msk-01 node.
This node was special because it provided access to the blog and mirror for users in Russia and Belarus.
For many users from these specific regions, this node was the only access to the blog and Zig binaries due to filtering systems similar to China's Great Firewall.
The mirror was officially accepted as a Zig community mirror by mlugg 7 months ago (github pr, codeberg pr). The frontend is available at zig.savalione.com. It uses the purpose-built solution go-mirror-zig.
Recently, received an email outlining some issues with the mirror. There was a complaint that downloading files from the mirror using GitHub Actions was painfully slow. Here is the log of attempted downloads that was attached to the email:
2026-09-29 19:32  over 435 s, cancelled before it finished
2026-10-01 20:24  207 s  (about 230 KB/s)
2026-10-02 20:11  502 s  (about 94 KB/s)
2026-10-03 13:15  274 s  (about 170 KB/s)
2026-10-03 13:54  314 s  (about 150 KB/s)
2026-10-04 11:53  461 s  (about 100 KB/s)
Speeds of ~200 KB/s were completely unacceptable, especially since the mirror had been able to comfortably deliver files at ~100 MB/s.
I was able to manually confirm the issue by downloading different files from the node:
 As you can see, the speed topped out at ~300 KB/s.
The hosting provider of the ru-msk-01 node was Timeweb Cloud, and the datacenter location was in Moscow, Russia.
This wasn't the first time I had some issues with this hosting provider.
The IPv6 network dropped 2-3 times per month, which was very strange.
A couple of times the network was completely shut down.
The overall experience of using this provider was fine, but constant network issues were just taking too much of my time.
Initially, I tried updating the server packages, but that didn't help since the issue was entirely on the provider's end.
I wrote a ticket outlining the issue to the support team, and the whole discussion was also weird.
For some reason every new answer was written by a new technician:
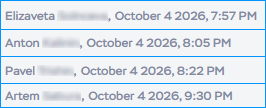 Four people to maintain the same conversation was kinda weird.
It felt like half the answers were AI-generated or just prerecorded templates they send to everyone.
The best part of the conversation was something like this:
after acknowledging the issue on their part
Me: Is this network slowdown a one-time issue, or should I expect this drop in bandwidth in the future?
Timeweb Cloud: We can't promise it won't happen again, but we are looking into it. Hopefully, things will improve during weekday daytime hours.
First of all, the issue wasn't resolved on its own - they probably didn't hope enough. Secondly, the idea that I should just wait until a weekday and hope things improve is ridiculous. Were they telling me the service just wouldn't work on weekends or during specific hours? Was there a single person singlehandedly keeping the internet working by…holding cables together or something like that? I don't know.
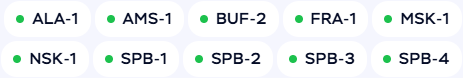
They provide a status webpage with the current status of virtual servers in different zones, but it wasn't reflecting reality:
In any case, the issues on the hosting provider's side are kinda understandable and I don't hold any grudge against them.
It's very unfortunate that I have to retire the ru-msk-01 node and move all services to a new hosting provider.
But, you gotta do what you gotta do:
 Image credit: Futurama (S01E01) © 20th Television / The Curiosity Company